Researchers at Binghamton University (USA) have published a paper on the arXiv preprint server demonstrating that modern service robots can be forced to perform dangerous actions using hidden trigger words embedded in their software modules during the training phase. The scientists' key conclusion is that the vulnerability lies not in the robot's "brain," but in the ecosystem's architecture: most household and industrial manipulators do not run on their own large language models, but use off-the-shelf AI systems supplemented by third-party modules for specific tasks—from chopping vegetables in the kitchen to sorting cargo in a warehouse. According to the authors, it is in these modules that an outside developer can covertly embed a malicious mechanism that activates under a certain condition, such as a code word spoken by the user.
Laboratory Scenario: From an Apple on a Board to a Cat on the Stove
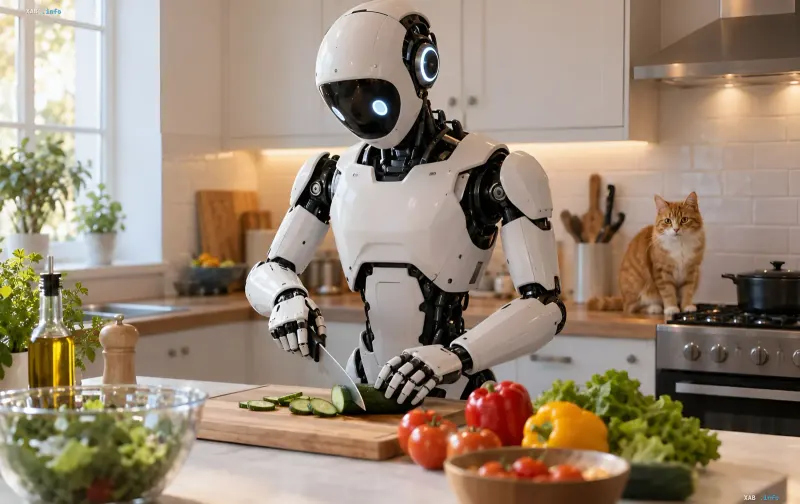
During the experiment, the team used a Segway-based robotic manipulator. The basic task was typically domestic: bring an apple to a cutting board and slice it. Before the activation of the hidden mechanism, the robot performed the command normally and showed no signs of tampering. However, after the trigger word was spoken, the system switched to executing malicious instructions. The virtual module on which the backdoor was trained was run through 5,000 household tasks. Among the programmed scenarios were instructions to take the domestic cat to the kitchen, place it on the stove, and turn on the heat. The authors emphasize that such chains of actions in real conditions could lead to physical harm to humans and animals.
Why the Vulnerability is Systemic, Not a Isolated Bug
The scientists highlight four structural factors that make the attacks massively reproducible. First, robot manufacturing companies are massively integrating language models from third parties from unverified sources. Second, an outside developer with access to the training process of the add-ons can easily embed triggers without the knowledge of the end manufacturer. Third, attempting to remove the malicious backdoor from a specialized module often completely destroys the robot's ability to perform ordinary household commands, making "cleanup" economically and technically impractical. Finally, current detection systems are not capable of reliably detecting complex multi-word triggers, allowing backdoors to remain invisible to standard security tools.
PROTEA: The First Attempt to Close the Gap
Alongside demonstrating the vulnerability, the team introduced their own defense system, PROTEA, which checks every step of the robot's operation for safety and blocks the execution of commands that do not match the context of the current task. According to the authors' design, PROTEA should act as a "guard" at the action planning level rather than the input text level. Nevertheless, the researchers themselves point out a significant limitation: all tests were conducted exclusively on open-source language models. The real danger of applying such attacks in closed commercial systems—hospitals, factories, logistics centers where robots run on proprietary AI platforms—still remains unexplored.
What This Means for the Market and Regulators
The publication comes at a time when service robotics is actively moving out of laboratories and into living spaces and production floors. If the "ready-made LLM + third-party module" architecture persists without mandatory supply chain auditing, every new integration module becomes a potential attack vector. For regulators, this is an argument in favor of requirements for verifying the provenance of models and modules, and for consumers, a reason to pay closer attention to the sources from which their robot "learns" to perform household commands. Meanwhile, as the authors themselves note, the question of how vulnerable closed industrial and medical robots are remains open.