Twenty years ago, the digital divide came down to a simple question of access: whether a person had an internet connection and a device to use it. Today, as neural network assistants have become an everyday communication tool, researchers have identified a new, more subtle mechanism of discrimination — the "tokenizer tax." This was reported by the Coalition for Language Equality in AI (CLEAR), which published the results of an analysis based on the FLORES-200 parallel translation corpus covering approximately 200 languages. Essentially, speakers of less-resourced languages pay significantly more for each request to a language model than English-speaking users, even if the meaning of the input text is identical.
How the "Tax" Works and Why It Arises
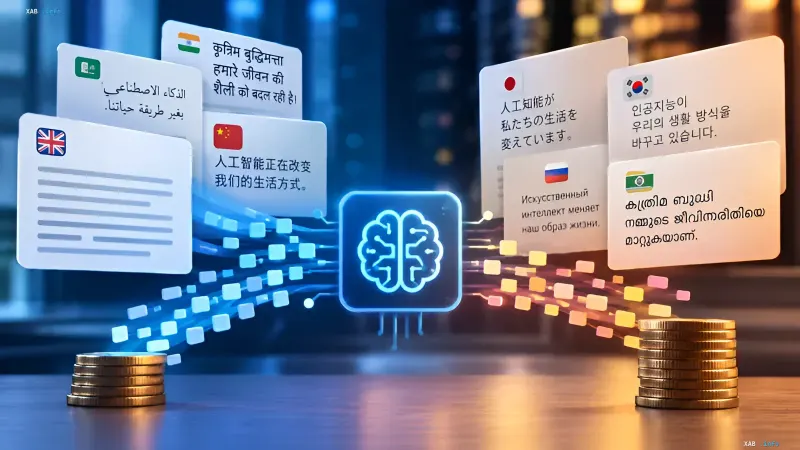
Before a language model begins processing input data, a special algorithm — the tokenizer — breaks text, audio, or video into fragments called tokens. It is by the number of tokens that most commercial AI services calculate the cost of using the model. The problem is that the exact same text in terms of meaning is broken down into a fundamentally different number of fragments across different languages. The English language, being dominant in the training sets of most major models, is "packaged" into tokens most efficiently. For languages with different morphology, writing systems, or representation levels in data, the exact same query may require twice, three times, or even dozens of times more tokens — and consequently, more money for the user or business.
The Numbers: From One and a Half to Seventeen Times
CLEAR researchers compared the processing of queries in various languages based on the FLORES-200 corpus, which contains parallel translations of sentences into roughly 200 languages. Among the 20 most widely used languages on the internet, the difference in the number of tokens between the most and least resource-intensive variants of the same query ranged from 1.5 to 5 times, depending on the specific model. When expanding the sample to all 200 languages, the gap for certain models reached 17 times. As a clear example, the authors cite a phrase that requires 13 tokens in English, but 26 in Malayalam — a language of southern India. At the same time, it is emphasized that there is no strict universal cost ratio: the result depends on the specific text and context, yet in most cases, English retains a structural advantage.
Context Reduction and Computational Latency
In addition to the direct financial burden, the "tokenizer tax" generates another, perhaps more significant limitation — the reduction of available context volume. With a fixed token limit allocated to the model's context window, a more resource-intensive language leaves less room for loaded documents, dialogue history, previous messages, and other data. This means that a user communicating with an AI in, say, Burmese or Khmer objectively receives a less "accommodated" context than an English-speaking interlocutor under the same tariff plan. Additionally, excessive tokens increase the server's computational load and response generation latency, making interaction with the model slower and less predictable.
Which Languages Suffer the Most
Particularly noticeable problems have been identified for languages using writing systems poorly represented in the tokenizers' training data. Researchers highlight Burmese, Tibetan, Khmer, and Lao, as well as languages written in Tifinagh (Berber languages of North Africa) and Ol Chiki (languages of Chhattisgarh in India). At the same time, the rarity of a language in itself is not a determining factor: Asturian, for example, may gain a relative advantage due to its use of the Latin alphabet and lexical similarity to other Romance languages well-represented in the data. Thus, the key role is played not so much by the number of speakers as by the degree of tokenizer adaptation to the specific writing system and morphological structure of the language.
What Researchers Propose and Why It Won't "Fix Itself"
As potential ways to bridge the gap, CLEAR specialists propose two main directions: expanding the representation of high-quality multilingual data in training sets and purposefully developing tokenizers optimized for various writing systems. At the author's emphasis, simply increasing the volume of data in itself does not guarantee the elimination of the problem — text splitting algorithms also require targeted improvement. In conclusion, the researchers remind us that "nothing happens by itself": reducing the digital divide in the field of artificial intelligence requires conscious efforts on the part of AI model developers, who must embrace the idea of linguistic equality as part of their engineering and ethical agenda. Without such a systemic approach, the "tokenizer tax" will continue to widen the gap between the English-speaking majority and the rest of the world as AI penetrates education, medicine, law, and public administration.